Why Computer Vision Models Fail Without High-Quality Image Data
Computer vision systems are only as reliable as the image data used to train them. While model architectures continue to advance, many failures still trace back to poor visual inputs. Low resolution, inconsistent lighting, incomplete labeling, or missing context can all degrade performance long before a model reaches deployment.
High-quality image data provides the visual clarity models need to accurately detect, classify, and understand objects in real-world environments.
Resolution Directly Impacts Detection Accuracy
Fine details matter in computer vision. Edge definition, texture, orientation, and spatial relationships all influence how models interpret visual scenes. Low-resolution imagery often forces models to infer missing information, increasing false positives and misclassification rates.
High-resolution images preserve these details, enabling more precise object detection and more reliable scene understanding across varied use cases.
Metadata Turns Images Into Training Signals
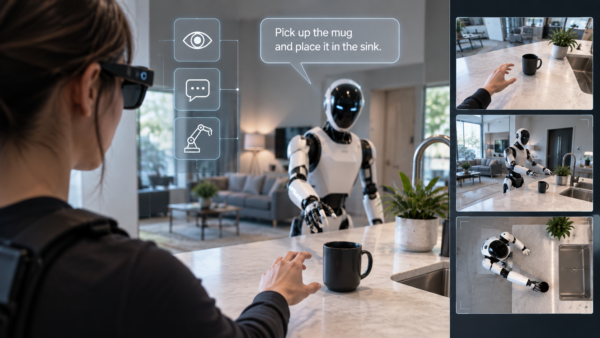
An image alone is not enough. Structured metadata, such as object labels, bounding boxes, orientation, and environmental context, transforms raw visuals into usable training data. Without consistent metadata, even large image datasets can produce uneven or biased results.
Well-labeled image data allows teams to isolate errors, retrain specific classes, and adapt models without rebuilding entire datasets from scratch.
Real-World Variability Improves Generalization
Models trained exclusively on controlled or studio-style imagery often struggle in uncontrolled environments. Shadows, reflections, clutter, and lighting changes introduce complexity that static or overly clean datasets fail to capture.
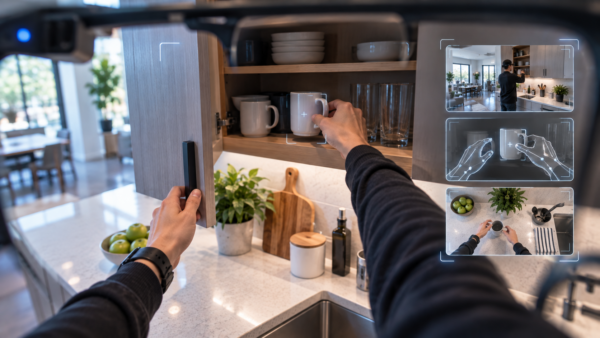
Including images from both controlled and natural scenes improves generalization, helping vision models perform reliably once deployed beyond ideal conditions.
Building Strong Vision Models Starts With the Right Images
Effective computer vision requires datasets that reflect how the world actually looks, not simplified approximations. High-resolution imagery combined with structured metadata provides the foundation for robust object detection, classification, and segmentation.
MatchPoint AI supports teams building computer vision systems by capturing professionally produced image datasets with precise metadata, helping models learn from clear, consistent, and realistic visual inputs.